
The most repeated landing page advice is still the same: rewrite the headline, recolor the button, and call the next week a test. That advice fails when the page never records a lead, the form rejects a real phone number, or the offer on a phone screen never becomes readable. Landing page conversion rate optimization is a revenue system. Judge the page by qualified leads, closed revenue, and downstream return on ad spend, not by clicks or raw form starts.
A pretty variant cannot rescue a page that loses data. Fix what blocks the sale first. Then test one change against a guardrail. If traffic is thin, which it is for many local and service businesses, do not pretend a two-day split test is proof.
Audit Your Landing Page Before Changing Anything
Spend the first 30 minutes on the live page, once on a phone and once on a desktop, before anyone touches copy. I would start with the failures that stop leads entirely: broken tracking, form errors that block submission, and a mobile page that loads too slowly to read. Sequence matters. A test cannot tell you anything useful if half the conversions never reach analytics, so broken items go first and wording questions wait.
Walk the checks in this order. A pass signal is a behavior you can observe, not a design opinion.
| Check | What to look for | Pass signal |
|---|---|---|
| Load speed | Time until the main content is visible on mobile | Main content is readable within about 3 seconds on the phone customers use |
| Message match | Whether the headline repeats the ad or search promise | The same offer is visible in the first screen |
| Primary call to action | Number of competing buttons above the fold | One specific button visible without scrolling |
| Form length | Count of required fields | Every field is used to qualify or route the lead |
| Form errors | Result of submitting a deliberately invalid entry | The message names the field and the fix |
| Tracking | Test lead sent through the form and checked in analytics | Conversion fires once with campaign and page data attached |
| Tap targets | Buttons and fields tapped with a thumb on a phone | No misses or accidental taps |
| Trust signals | Testimonials, claims, and logos near the call to action | Proof is real, dated, and specific |
Score the failure, not the screenshot
Say a local HVAC page uses a seven-field booking form, and the headline never mentions emergency repairs. The audit finds two blocking issues and one unclear offer before any experiment is planned. Tracking drops the campaign name, so paid leads look like direct traffic. The form rejects a valid mobile number and shows only "invalid input." The headline promises a seasonal tune-up while the ad promised same-day heat. Those are not equal problems.
Score each failure by the share of visitors it affects, not by how annoying it looks in a screenshot. A tracking break hits every paid visitor. A rare logo complaint hits almost none. A slow hero image may hit only mobile, which can still be most of the traffic.
Run every check on the phone your customers use. Desktop reviews miss thumb misses, tiny fields, and keyboards that cover the submit button. The deliverable is a one-page list of failures ranked by impact. That list is the hypothesis backlog for later tests. If you want a structured pass before you change the page, use this conversion rate optimization audit.
Practical rule: If the page cannot record a completed lead with campaign and page data attached, do not change the headline yet.
Benchmarks That Show Whether Your Rate Is Weak
A page can beat the median and still lose money. A median is a benchmark for context; your own baseline decides the target. A 2024 landing-page benchmark compilation covered roughly 41,000 landing pages, 464 million visitors, and 57 million conversions, and put the median conversion rate at 6.6%. Use that figure as a sorting tool. It tells you which pages deserve a closer look, not which pages are healthy.
Industry medians move with offer type, traffic temperature, and the action you count as a conversion. Warm traffic sits in a different band: Unbounce's conversion benchmark report put email-referred visitors at an average of 19.3% in 2024. Compare email pages with email pages, paid search with paid search, and demo requests with demo requests. A blended rate across those sources hides the page that is broken.
| Segment | Reported rate | How to use it |
|---|---|---|
| Cross-industry median (2024 benchmark) | 6.6% | Directional reference for spotting unusually weak or strong pages |
| Email-referred visitors | 19.3% | Warm-traffic reference; compare email pages separately from paid traffic |
Write the segment down before you judge
Before you call a rate weak, record five facts: the conversion definition, the traffic mix, the device split, the campaign intent, and the time period. An e-commerce product page, a local-service lead form, and a software demo page should not share one success threshold. A modest demo-page rate can be ordinary for software. The same rate for a high-intent emergency service, fed by search ads, is a different problem.
A page far below its own segment median deserves the audit above. A page near the median is not automatically healthy. Only a controlled experiment tied to qualified leads and revenue shows whether a change helps the business. Raw rate movement can hide worse leads. A higher conversion rate that brings in poor-fit leads and weak downstream ROAS is a loss dressed up as a win.
Before any work begins, write down three baseline numbers: the current rate, the monthly sample size, and the date range those numbers cover. Every later result needs that comparison, or you will argue with a moving target. When the monthly sample is too small to separate real lift from noise, use the benchmark to prioritize fixes, not to declare winners. For a plain explanation of how to read a rate against your own offer, see what counts as a good conversion rate.
A page at the median can still waste ad spend if the leads are unqualified or the margin disappears after the sale.
Form, Copy and Layout Fixes That Stop Abandonment
Field-count advice starts in the wrong place. Track the form in stages, or you will fix the wrong half of the drop-off. A Clutch summary of Zuko's benchmark covered 739 forms and 93 million form views from January 2022 through April 2025. The average view-to-completion rate was 34.6%, while the starter-to-completion rate was 51.7%. The same report puts e-commerce forms at 35.8% view-to-completion and 51.0% starter-to-completion, and financial-services forms at 35.7% and 58.4%. Read those stages as different problems. A low start rate is usually a visibility or motivation problem above the form. A low finish rate is field friction, unclear expectations, or distrust inside the form.
A completed form is an intermediate event. The number that matters is qualified leads that become revenue, with downstream ROAS as the check. A two-field form that asks for a sensitive detail can lose to a longer form that feels relevant to the job. Shorter is not automatically better. I would fix a weak start rate before polishing the submit button, because no button test rescues a form few visitors begin.
Meet the visitor in order
Place one specific value line above the form. Name the outcome in the button, such as Get my quote, not Submit. State what happens next, such as a reply within one business day. That sequence matches how a visitor decides: offer, action, expectation. Then tighten the form itself.
- Error text: Place the message beside the field, and name both the field and the fix.
- Phone versus email: Keep the phone field optional when email is enough to qualify or route the lead.
- Spam gates: Skip CAPTCHA on lead forms unless spam is already flooding the inbox.
- Layout: Use one column, keep labels visible above the fields, and place the button where the eye lands after the last field.
Checkout cost and access
Checkout abandonment is a cost and trust problem before it is a styling problem. Baymard's abandonment research found that 40% of surveyed users abandon because of unexpected additional costs, 18% because they are forced to create an account, 17% because checkout is too long or complex, and 9% because a preferred payment method is unavailable. The wider benchmark combined 272 moderated test sessions, eye-tracking, more than 850 checkout steps, and nine quantitative studies totaling 11,777 participants, as Baymard's checkout benchmark describes. Show the total price early, allow guest checkout, cut default steps, and offer payment methods buyers already use. Judge completed purchases and revenue per session. A modeled uplift from checkout design is a directional opportunity for large stores, not a promise for every page.
Treat accessibility as conversion work and compliance work in one pass. A Figma resource-library summary reports detectable WCAG failures on 94.8% of the top one million homepages. Check contrast, labels, keyboard access, and error text, then measure form completion and qualified leads by device. Accessibility removes barriers; the lift depends on which barrier your visitors hit. Offer language belongs in the same pass as the form. Use copywriting in advertising to name the outcome and the next step rather than the company's mood.
How to Run a Hypothesis-Driven A/B Test
A hypothesis names observed friction, a single change, and the business result you expect. Point to the friction in a session replay, a form field, or a sales call before you write the sentence.
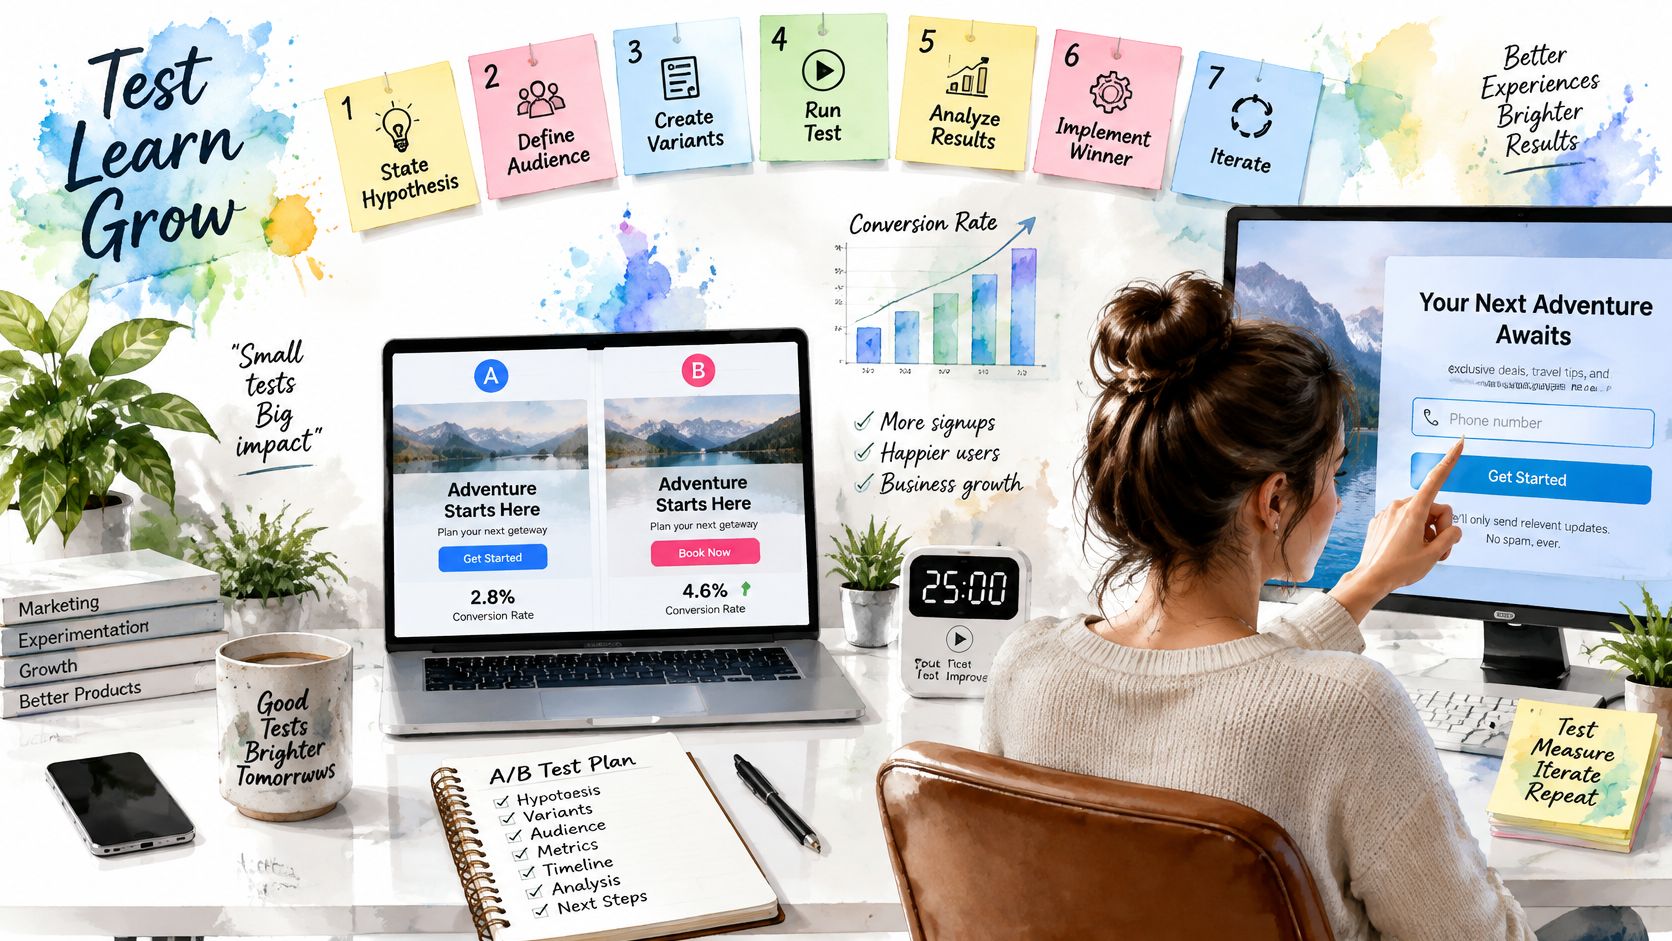
- Write the hypothesis from observed friction. Use a sentence you could disagree with. "Visitors stop at the phone field because they expect a callback, so offering a callback time should raise completed leads." A preference for blue belongs in a design review, not a test plan.
- Lock the metrics before launch. The primary metric is a completed, revenue-generating conversion. Pick one secondary metric, such as qualified-lead rate or average order value. Pick two guardrails, such as refund rate, lead quality, or page latency. When the sale closes later, follow the cohort through to revenue or downstream ROAS. A click lift with a quality drop is a loss.
- Set the sample size and the stopping rule first. Decide how many conversions, or how many days, end the test. Peeking after a strong Monday inflates false positives, and thin samples make that temptation worse. A test that ends on three conversions has not measured a page; it has recorded a week.
- Split traffic between a control and one variant. Change one element so you can attribute the result. Two changes at once give you a winner you cannot explain, which means you cannot repeat it.
- Run until the pre-set threshold. A hot first few days are not a result. Stopping early is how teams ship noise and then spend a quarter explaining the reversal.
- Segment by device and acquisition channel. A winning mobile variant can hide a desktop loss, and paid search can move while email does not. Report the segments even when the blended number looks clean.
- Log the decision, the result, and the learning. Put it in the backlog the same day. The next test should build on evidence, not on what someone remembers from a meeting.
What a failed guardrail looks like
A headline test lifted button clicks and cut qualified leads. Sales spends more time on people who wanted a coupon, not a booking. The guardrail catches that before the change ships. Do not ship it, even when the blended conversion rate looks better in the dashboard. When the primary metric and a guardrail disagree, the guardrail wins until you can explain the gap.
For the design of the split itself, including what to hold constant, follow a written experiment design rather than a slide of button options. One change, one primary metric, one stopping rule. That is the whole discipline.
Testing Landing Pages When Traffic Is Too Low
A page that produces 40 leads a month will never give you a clean split test in two weeks. That is normal for local services. A 2025 survey of 264 marketers at businesses with 500 or fewer employees found 41% named insufficient traffic as a major optimization challenge, and 37% cited limited time or resources to build and test variants. Forcing a standard A/B process on that volume trades accuracy for activity.
Fix what does not need a sample. Slow loading, broken tracking, unclear form errors, and message mismatch sit at the top. Take a dental implant page doing 40 leads a month. The mobile form rejects valid phone numbers with a generic "invalid entry" message. You log six failed submits in call tracking and form replays, you fix the validation and add a clear error state. That ships without a p-value. No test would make the decision stronger.
Match the method to the volume, and name its limit. Sequential testing with a predefined limit stops you from chasing a lucky week, but it is still sensitive to seasonality. Pre and post analysis with guardrails can work when you change one known defect and watch refunds, lead quality, and latency, but a concurrent campaign change can fake the lift. A Bayesian decision rule can update as leads arrive, yet a prior you invent to force a winner is still a guess.
Pool evidence without pretending the pools are identical. Similar campaigns, locations, or audience segments can share a pattern, such as the same broken phone field. They are not one population. Keep the segments visible when you combine them. I would not average a roofing page with a dental page to manufacture a sample, because the intent and ticket value pull the revenue math in different directions.
Many SMB teams now use AI for design suggestions, draft copy, and personalization. Use it to clear the backlog faster, then hold every output to downstream result. A variant that raises raw submissions while filling the pipeline with price shoppers fails the only test that matters for a revenue system.
Metrics That Prove Real Lift, Not Vanity Wins
A landing page earns its keep downstream of the form. A submission is a lead, not a sale, so judge every variant by what happens after the form is filled. Pair each business metric with the guardrail that can block a false win.
| Metric | What it tells you | Guardrail |
|---|---|---|
| Qualified-lead rate | Share of submissions that meet sales criteria | Lead volume must not fall below the baseline |
| Revenue per visitor | Revenue earned for each landing page visitor | Measure separately for each traffic source |
| Average order value | Basket size of converting visitors | Watch discounts that lift conversions but shrink margin |
| Refund rate | Post-sale reversals tied to the page's promise | Must not rise after the change |
| Downstream ROAS | Advertising return after the lead or sale | Compare against the pre-test period |
| Page latency | Load time of the winning and losing variants | Winning variant must not load slower than the control |
Revenue per visitor needs a far bigger sample than click-through rate before it clears noise. On a page pulling a few hundred visitors a month, read the guardrail's direction across rolling four-week windows, not one week's spike. A refund-rate blip after eleven sales is not a signal.
Credit the path, not only the last click
Google's attribution documentation separates attribution from simple conversion counting. An attribution model decides how credit is split across ads, clicks, and other touchpoints. Data-driven models use observed data to estimate each touchpoint's contribution. Privacy-safe modeled conversions fill gaps where a user cannot be observed directly.
A variant can look weak under last-click reporting because it assists a later branded search, a phone inquiry, or a return visit. A service page explained price and timing clearly, and fewer visitors submitted on the first visit. More of them searched the brand the next morning and called. Last-click hands the credit to the brand query and calls the landing page a failure.
Define the conversion event, keep campaign and landing-page parameters on every submission, and compare variants under one attribution model for the whole test. Switching models mid-test is how a flat result becomes a story. With consent, enhanced conversions can hash first-party email, phone, and address data and match it when cookies are missing, which improves cross-device measurement so you judge outcomes rather than clicks. The measurement guide for enhanced conversions is the mechanic. Consent comes first. Hashing happens before transmission.
We test, measure, and optimize campaigns rather than guessing, and the same rule applies to every page: a variant that raises the top-of-funnel metric and lowers a guardrail does not ship. Read results next to ad performance metrics that still mean money after the lead is handed to sales.
Book a Growth Consult to Turn Your Audit Into Revenue
The audit only pays if someone owns the fixes. Rank the failure list, assign each item to a person with a date, and put the tracking repair at the top. A page with a broken conversion event cannot be optimized, because every later test returns noise.
Before the consult, bring four things: the ranked failure list, the current conversion rate with its sample size, the last four weeks of qualified-lead counts, and the variant backlog with the hypothesis written out for each entry. A consultant can work without them, but the first hour goes to rebuilding what you already know.
Two situations justify outside help rather than another internal sprint. The first is a measurement problem you cannot isolate, such as a form that fires a conversion in one analytics property but not in the ad platform, or consent settings that suppress enough data to make small-sample results unreadable. The second is a traffic ceiling: when a page gets too few qualified sessions per week to reach significance in a reasonable window, the answer is usually a sequence test or a change to the offer, not another button color.
If either applies, request a demo through the Request a Demo or Book a demo buttons. Come with the ranked list, not a request for a full rebuild.
Ad Suite Membership members receive a 25% discount on all products and services, priority access to the team of experts, and access to the in-house CRM and Review Management Software. That combination matters for CRO specifically: the review software feeds proof back into the page, and the CRM shows which leads closed, so the next test is judged on revenue rather than form fills. Membership runs $400 per year, which is worth weighing against the cost of a single stalled test cycle.
One caution before you book. A consult produces a plan, and a plan is not lift. The gain shows up when the ranked list shrinks week by week and the qualified-lead count moves against the same measurement you started with.
The Advertising Suite is a growth-focused partner for landing page conversion rate optimization, tying tests to qualified leads, revenue, and downstream return rather than clicks. If your audit is stuck on tracking gaps or thin traffic, visit The Advertising Suite and book a growth consult so the work sits with your team, not beside it.